Read the scope before the percentage
Before asking whether a number is high or low, review the questions, environment, date and coverage behind it.
A diagnosis does not estimate every conversation occurring in a tool. It does not describe the behavior of another interface or model by itself.
Make the denominator visible
A presence percentage needs a definition of valid answers and an explicit observation count. Execution failures and incomplete answers belong in the coverage record.
Changing a denominator can change the percentage even if mention counts stay the same. Document both values.
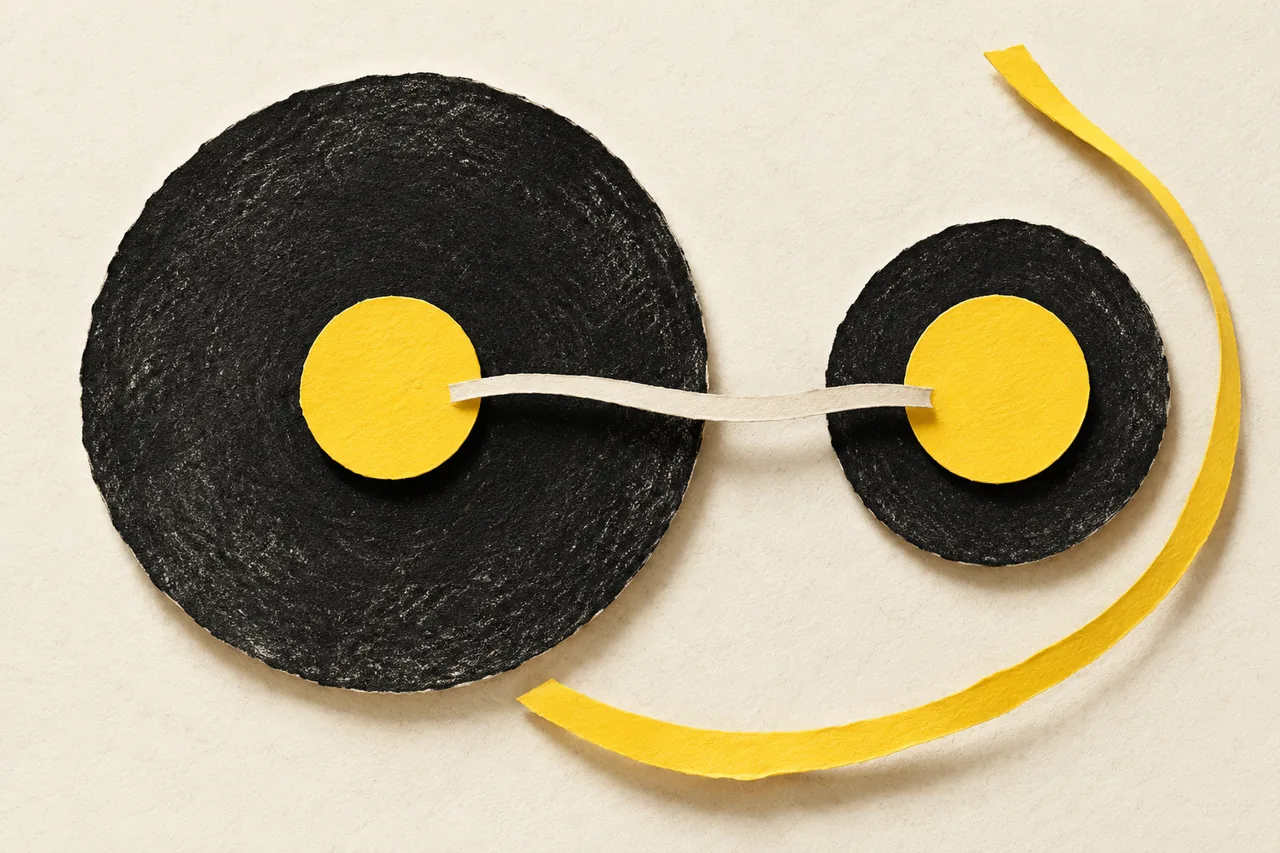
Twice the percentage. The same six mentions.
6 mentions in 20 valid answers. Coverage: 20/25.
6 mentions in 10 valid answers. Coverage: 10/25.
The case: 30% and 60% can describe the same count
In the figure’s exercise, 25 observations are planned for each period. A produces 20 valid answers and the brand appears in 6: 6 ÷ 20 = 30%. B produces only 10 valid answers, also with 6 mentions: 6 ÷ 10 = 60%. The percentage doubled; the mention count stayed the same.
Coverage dropped from 80% to 40%. We do not know what the missing answers would have said. Counting them as answers without a mention would hide the failure; dropping them without showing coverage would hide another part of the problem. Before interpreting the change, investigate the errors and the questions that actually received answers.
Return to the rows: did the same intents fail, was the surface preserved and which questions have an answer in both periods? A common subset may help the comparison, provided its size and exclusions are visible.
Compare compatible conditions
Two captures may use different questions, languages, models or search modes. Their difference may reflect those conditions as well as any content change.
Keep a common question version, identify environments and record dates. Explain any changed condition before interpreting the comparison.
- Same objective and comparable question set.
- Preserved language and context, or documented changes.
- Identified environment and model where possible.
- Visible coverage, errors and calculation rules.
- Reviewable answers and sources behind the summary.
When the comparison does preserve the sample
Now suppose another exercise with compatible conditions and 20 valid answers in both periods: the brand goes from appearing in 6 to appearing in 9. Presence moves from 30% to 45%. That is a difference of 15 percentage points, or a relative increase of 50%. Both are arithmetically correct, but need the count beside them to be interpretable.
Even that difference does not prove an intervention caused it. Answers can vary between runs. Record the planned repetitions and avoid treating similar rewordings as independent people. This sample measures neither market share nor the frequency of all conversations.
Distinguish observation, hypothesis and effect
Observation: the brand appeared in more sample answers. Hypothesis: a content improvement may have contributed. Causal conclusion: that intervention produced the change. The third requires a design that evaluates other explanations.
A before-and-after comparison helps follow change, but the model, available sources and answers may also change between runs. Avoid automatically attributing movement to an action.
Document a reviewable decision
A useful priority names its supporting answer, the source to review and a proposed next step. Where evidence is insufficient, investigate further.
Keep visibility outcomes separate from visits and commercial inquiries. The full chain needs different observations and is not established by a mention.
A decision note your team can discuss
Try four lines: what we observed, the evidence, the explanation we are considering and what we will inspect. For example: “In the comparable sample, three additional answers mention the brand. We will review their sources and brand descriptions before proposing changes.” That note can be challenged and avoids turning an association into a cause.
If the question is whether visits or enquiries arrived, open that analysis in its corresponding sources. Google explains that traffic from its AI features is included in overall Web search performance in Search Console. That report and a record of observed answers describe different populations; one does not automatically validate the other.